GuideAI in production
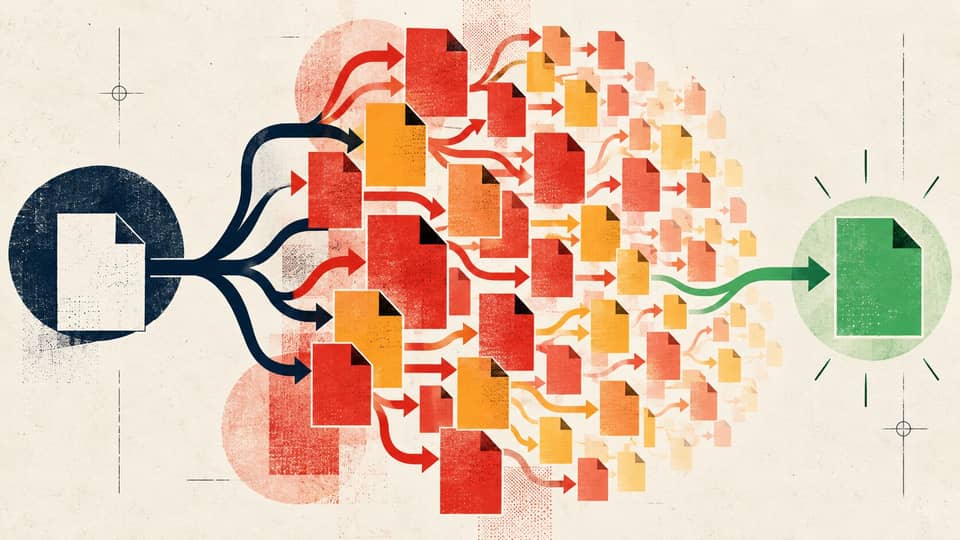
Measuring retry amplification in AI agent workflows
Connect logical tasks to every model and tool attempt, then measure cost and latency per accepted outcome without hiding failed or unknown work.
Guides, news and explanations about AI and reliable systems.
Connect logical tasks to every model and tool attempt, then measure cost and latency per accepted outcome without hiding failed or unknown work.
Measure cached input against total input, locate the prefix miss boundary, and judge cache changes beside latency, task cost and correction work.
What prompt-cache hits save once retries and failed work are included in task cost, with a local calculator and ledger.
GPT-6 Sol and Luna combine lower token rates with cache-write and cache-read pricing. A repeated prompt can cost less even though its first cached write carries a premium.
An approved summary task can take a new data path when a connector is added. Account controls, retention and output sharing apply at different points along that path.